
- July 7, 2026
- 9 min read
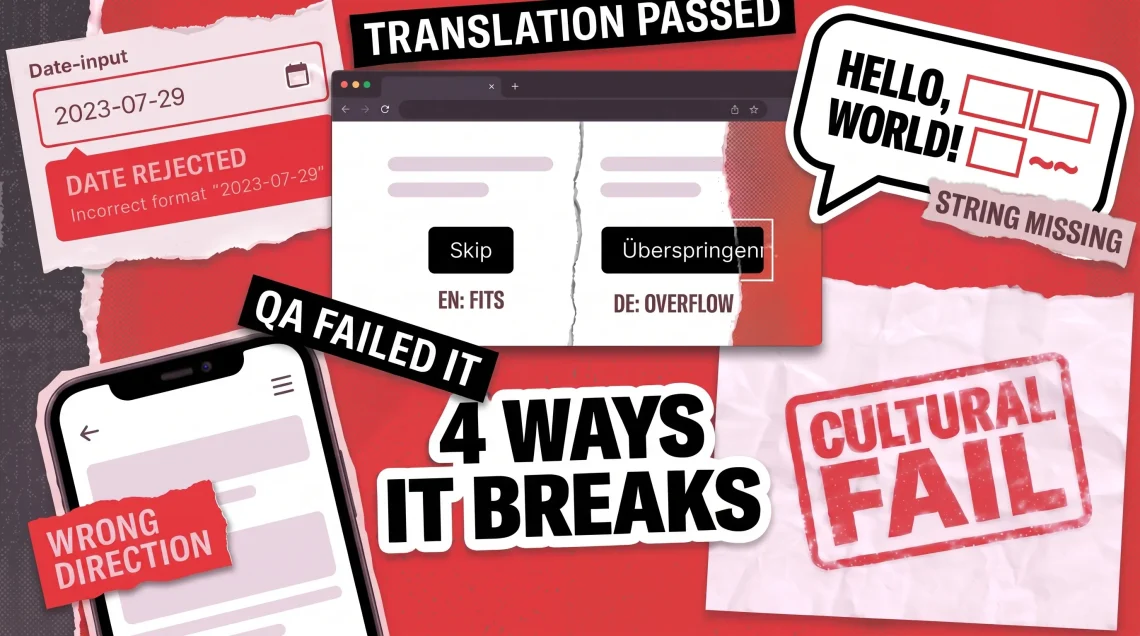
When a product ships into a new language, the thing that breaks is almost never the translation by itself. The words are usually fine. What breaks is the button that no longer fits them, the checkout that rejects a local date format, the screen that stays left-aligned when it should mirror, and the color that means something very different in the market you just entered. Catching those problems is the job of localization QA testing, and it is the reason teams running serious global launches bring in dedicated localization testing services before release rather than after the one-star reviews arrive.
- July 7, 2026
- 12 min read
Most localization testing guides hand you a phase list and call it a day. Plan, design, execute, retest. The problem is that you finish reading and still have no idea what an actual test case looks like, what bug to expect in German versus Arabic versus Japanese, or whether your coverage is enough to ship.
- July 6, 2026
- 10 min read
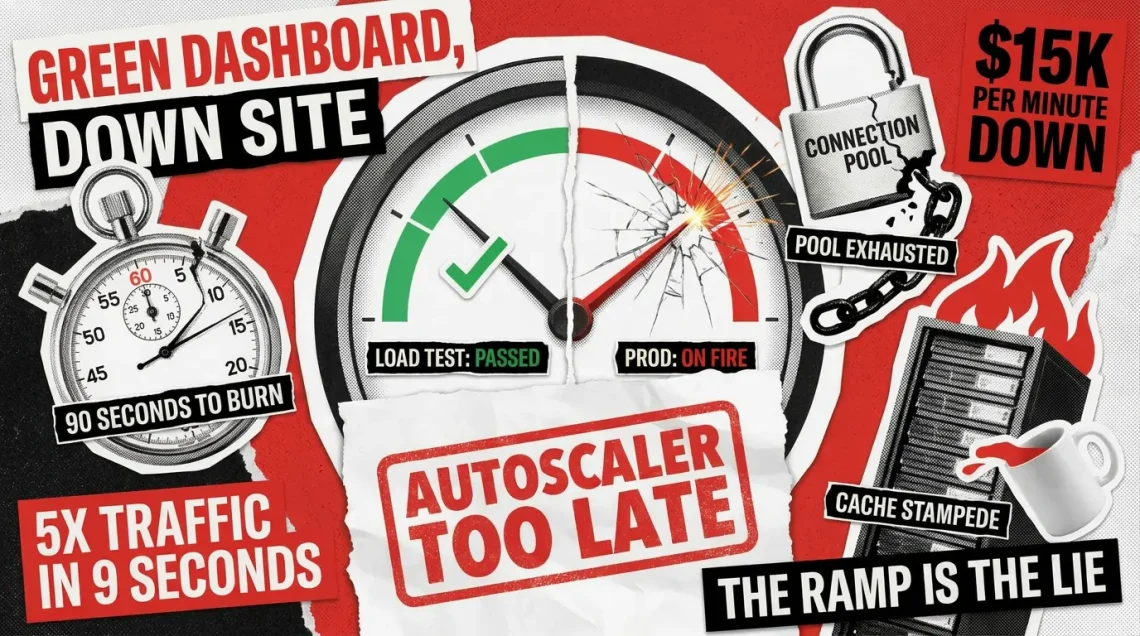
A load test runs to ten times steady traffic. Every threshold green. Every SLO met. Two weeks later, a Product Hunt feature pushes traffic to roughly twice baseline in ninety seconds. P99 latency jumps from 180 ms to 14 seconds. Error rate hits 38%. The autoscaler is still spinning up replicas after the burst has already passed.
- June 17, 2026
- 12 min read
Every app crash is a silent goodbye, and on mobile, users rarely give you a second chance. Mobile app crash reporting closes that gap by replacing guesswork with the exact details of what broke, on which devices, and for how many people.
- June 9, 2026
- 14 min read
Let’s imagine that you ship an AI product that nails every demo. Your team runs it through its paces before launch, and the outputs look sharp, so you ship with confidence. However, two weeks later, a customer sends you a screenshot of a response that is factually wrong, confidently stated, and completely at odds with what the same product said the day before. That could be a serious blow to your reputation, and you absolutely cannot afford to lose customer trust.
- June 2, 2026
- 10 min read
Air Canada lost a court case because its chatbot invented a refund policy. The tribunal ruled the airline had to honor what the bot promised. Klarna reversed its AI-first customer service strategy after its chatbot delivered worse service than humans, and started rehiring agents. Both stories made headlines because the underlying problem was the same. A large language model shipped into production without the QA process the technology actually needs.

- May 25, 2026
- 12 min read
Multi-agent AI systems sell a tempting vision: autonomous agents collaborating like a seasoned human team. In theory, this setup allows a specialized researcher agent to gather data, a writer agent to draft a report, and an editor agent to finalize it, all seamlessly communicating in the background.

- May 25, 2026
- 12 min read
Is your API not performing as expected? Are issues piling up, and you have no idea why, because it passed every test your team threw at it?
- May 22, 2026
- 13 min read
Let us face the harsh reality of the modern digital landscape. If your application goes down during a peak traffic event, you are not just losing a few conversions. You are burning through money and customer trust by the second. According to ITIC’s 2024 Hourly Cost of Downtime Survey, 90% of mid-size and large enterprises now lose more than $300,000 per hour of downtime, and 41% lose between $1 million and $5 million per hour.
- May 22, 2026
- 10 min read
Your CI pipeline turns red, someone clicks rerun, and the build comes back green on the second try. The PR ships, and nobody asks why the test failed the first time, because the team already has the answer ready: “it was flaky.” If this happens once a week, you have a problem worth naming.